Long-Tail AEO Content Strategy: Find the Follow-Up Questions AI Asks, and the Pages You're Missing
AI SEO
In Bing's sample, Microsoft Copilot cited GoGoChimp 2,036 times for "long-tail query content strategies answer engine optimization AEO", yet that's only a 9.40% share.
For a related query, "query cluster SEO Answer Engine Optimization AEO strategy", our share was 1.11%.
The AI wrote both strings. Bing defines grounding queries as "the key phrases the AI used when retrieving content that was referenced in AI-generated answers" (Microsoft Bing, 2026).
So in answer engine optimisation, the long tail is the set of follow-up questions the AI writes for itself, and you win or lose each one separately. You can find the ones you're losing with Rubric (our AI citability auditor) and Claude, then fix them without building a page per query. The wider playbook is in our AI SEO hub.
Why can a site earn 2,036 Copilot citations and still lose the long tail?
Because AI splits one topic into many phrasings and cites different sources for each. Bing Webmaster Tools logged 44,677 Copilot citations of gogochimp.com in the 90 days to 25 September 2026. Yet across five long-tail AEO grounding queries in Bing's sample, our share ran from 1.11% to 25.05%.
Which long-tail AEO queries does Copilot cite GoGoChimp for?
| Grounding query (Bing's sample) | Copilot citations of GoGoChimp (90 days to 25 Sep 2026) | GoGoChimp's citation share |
|---|---|---|
| long-tail query content strategies answer engine optimization AEO | 2,036 | 9.40% |
| long-tail queries content strategy Answer Engine Optimization AEO | 400 | 9.88% |
| high-value long-tail queries Answer Engine Optimization AEO | 114 | 25.05% |
| content strategies long-tail queries Answer Engine Optimization AEO | 73 | 19.89% |
| query cluster SEO Answer Engine Optimization AEO strategy | 48 | 1.11% |
Citation share is our portion of every citation Bing showed for that query. Bing doesn't reveal who holds the rest (Microsoft Bing, 2026). It also calls this data "a sample of overall citation activity" (Microsoft Bing, 2026), so none of these counts is a census.
Why does the share change when the words barely do?
Bing doesn't say why, so this is my reading of the table. Rows one and four use nearly the same words, yet our share is 9.40% on one and 19.89% on the other. So each phrasing behaves like its own search. I can't find a page of ours that answers "what is a query cluster" directly, which would explain why Copilot cites other sites for that phrasing.
In Bing's sample for the 90 days to 25 September 2026, Copilot cited GoGoChimp 114 times at a 25.05% share for "high-value long-tail queries Answer Engine Optimization AEO", and 48 times at 1.11% for "query cluster SEO Answer Engine Optimization AEO strategy".
Why does AI split one question into many searches?
To gather sources for each part of the question before answering. Google says AI Overviews and AI Mode "may use a 'query fan-out' technique, issuing multiple related searches across subtopics and data sources" (Google Search Central, 2025). OpenAI says ChatGPT search "typically rewrites your query into one or more targeted queries" (OpenAI Help).
In Bing's sample for the 90 days to 25 September 2026, 32,713 of our 44,677 Copilot citations came through 598 named grounding queries, the search phrases the AI wrote for itself.
How many searches does ChatGPT run per prompt?
ChatGPT ran about two searches per prompt through 2025 and early 2026. Ahrefs measured 1.78, with 75% of prompts triggering exactly two (Ahrefs, 2025). In April 2026, Peec AI counted 2.1 for ChatGPT, 1.4 for Perplexity and 6.8 for Grok (Peec AI, 2026).
Some measurements after ChatGPT's August 2026 model change show several times that rate, and others show no change. Nectiv re-ran about 4,000 prompts on GPT 5.6 Sol through OpenAI's API and averaged 7.61 searches per prompt (Nectiv, 2026). Nicolas Sitter's 616 hotel prompts showed a 0.7% change in fan-outs per chat (Sitter, 2026).
Does ranking for the sub-queries matter more than ranking for the prompt?
On the evidence so far, yes. Only 37.9% of URLs cited in Google's AI Overviews also sit in the original query's top 10 (Ahrefs, 2026). Surfer simulated fan-outs with Gemini for 10,000 keywords. Of the AI Overview citations that ranked at all, 51.2% ranked for the main query plus at least one fan-out, against 19.6% for the main query alone (Surfer, updated September 2026). Surfer says it's a correlation. Our Google AI Mode SEO guide covers Google's side.
How do you find the follow-up questions your site doesn't answer?
Run a Rubric audit and read three report sections: Conversation coverage, Fan-out readiness and Queries to check. Rubric predicts citability. It doesn't count citations. So use the report as a map of likely gaps, then check the real answers in ChatGPT and Perplexity. What a free account includes, and what Pro adds, is on the pricing page.
What does Conversation coverage check?
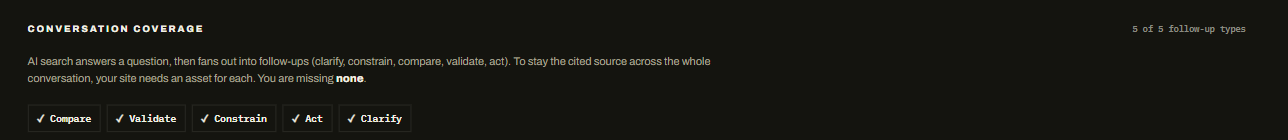
Ask a Glasgow taxi driver for the airport and you'll get five questions back. Glasgow or Prestwick? Any bags? Why aren't you getting the bus? You sure it's the six o'clock? Card or cash? Conversation coverage checks your site for an asset covering each of the same five follow-ups: clarify, constrain, compare, validate and act.
It detects them from page URLs, titles and headings, so it's a stock check: it reads presence, not quality. The report calls a missing Compare asset the costliest gap.
Ours shows 5 of 5, which sounds better than it is.
What does Fan-out readiness show?
Fan-out readiness shows coverage across ten sub-query types: entity, comparison, semantic, factual, attribute, follow-up, anticipate, perspective, transact and tutorial. Moz uses the same ten names for its fan-out categories (Moz, 2026).
Our report shows Comparison at 1 of 3 and the other types at 0. That's the same site that scored 5 of 5 on Conversation coverage, so read the two cards together.

Comparison matters in real AI answers too. In Nelson Brassell's Ten Speed study of B2B evaluation-stage prompts, 34 of 170 were comparisons (20.0%). Yet they drew 1,970 of 7,387 citations (26.7%), 1.33 times their share (Ten Speed, 2026).
What does Queries to check give you?
Queries to check lists likely sub-queries drawn from your own pages, pre-ticked, labelled by type and editable. They aren't a log of what the engines actually ran. Ours included "what is Rubric" (entity) and "Rubric alternatives" (comparison). The Copy for AI button copies them so you can run them in ChatGPT or Perplexity.
How do you map sub-questions to pages with Claude and the Rubric MCP?
Connect Rubric's hosted MCP to Claude and pull the audit with get_audit. Claude reads your pages through get_page and get_affected_pages and matches each sub-question to a page. The share-of-voice check stays manual: run the queries in ChatGPT and Perplexity, log the cited domains and give Claude the log.
How do you connect Claude to Rubric?
Create a key on Rubric's MCP page. It's shown once, so copy it before you leave the page. The same page gives you a one-line Claude Code command with your key already filled in. Run it in a terminal and Claude can read your audits.
Which prompt matches sub-questions to pages?
Paste this into Claude with your own list:
Use list_audits to find my latest Rubric audit for example.com, then get_audit, and summarise the scorecard. Then use get_page and get_affected_pages to read my hub, comparison, pricing and case-study pages. For each query below, name the page that answers it, and list the queries no page answers.
PASTE THE LIST HERE
How do you check share of voice by hand?
- Switch ChatGPT's memory off. OpenAI says "If memory is enabled, ChatGPT may use relevant saved memories when rewriting a search query" (OpenAI Help).
- Run each query in ChatGPT and in Perplexity, and log the date, engine, query and every domain cited.
- Repeat over several days, and score visibility as the share of runs that cite your domain.
- Keep each engine, and branded and non-branded queries, in separate columns.
Don't record a rank.
SparkToro put the chance of ChatGPT or Google's AI giving the same list of brands in any two of 100 responses at less than 1 in 100 (SparkToro, 2026). Peec AI's modelling says pinning a prompt at 50% true visibility to within 10 points takes about 100 runs (Peec AI, 2026).
Read the log like a weather forecast: it gives odds across many runs. A small log won't give you a precise share, but it will show the sub-question types where you never appear. Trackers automate the runs: see our guide to AI visibility tracking and our 2026 AI SEO tools round-up.
Then paste the log into Claude with this:
Group this log of ChatGPT and Perplexity answers by sub-question type. For each type where my domain never appears, name the existing page that should carry the answer, and say whether it needs a new section, a table or a separate asset.
How do you win back a lost sub-question without a page per query?
Cover each lost sub-question type with a section, block or asset inside a small set of useful pages. Google says creating separate content for fan-out queries "primarily to manipulate rankings or generative AI responses in Google Search violates Google's scaled content abuse spam policy" (Google Search Central, 2026).
Page count isn't the lever anyway. Across 75,000 brands, Ahrefs found almost no relationship between the number of pages on a site and AI visibility, a correlation of about 0.194. Branded web mentions correlated at 0.66 to 0.71 (Ahrefs, 2025).
Which fix matches which lost sub-question?
| Lost sub-question type | The fix | Where it lives |
|---|---|---|
| Definition or how-to ("what is X?") | A self-contained answer, or numbered steps, under a question heading | Near the top of the hub or guide |
| Comparison ("X vs Y") | A dated comparison naming both options and the trade-off | A vs-page if buyers compare you by name |
| Entity ("is this brand any good?") | One name, one category and the same facts everywhere | Homepage, About page and third-party profiles |
| Attribute or transact (pricing, specs, where to buy) | Current facts with a visible update date | Pricing or product page |
| Alternatives | An alternatives section | Inside the vs-page or hub |
| Validate (proof) | A named client, hard numbers and dates | A dedicated case-study URL |
In Brassell's Ten Speed data, product pages drew 24.1% of evaluation-stage citations, comparison pages 13.3% and how-to guides 8.9%. Dedicated alternative pages took only 2.4% (Ten Speed, 2026), which is why I'd fold alternatives into the vs-page. Our entity SEO guide covers the naming fix.
Should you build a comparison page for every competitor?
Only where buyers already compare you by name. Engines do generate comparison sub-questions. That doesn't make a vs-page a guaranteed ChatGPT win.
Dated evidence since ChatGPT's August 2026 model change is thin. In Nicolas Sitter's 616 hotel prompts, listicle citation share rose 7.6% (Sitter, 2026). That's one vertical, and it's listicles rather than vs-pages, so date your comparison page and re-run its queries after each model update.
What counts as proof for a validate question?
Proof means a named client, hard numbers and dates, on its own case-study URL. No third-party study we've found measures proof pages as a fan-out asset, so this is our own tracker data.
On 12 May 2026, when our BeeFriendly case was still anonymised on the blog, Perplexity told our tracker it couldn't find BeeFriendly. By 1 July 2026, Perplexity and Google AI Mode both cited our BeeFriendly Skincare case study for that query. That's one tracked query, so read it as a correlation.
What is a query cluster in AEO?
A query cluster is a group of related sub-queries close enough in meaning for one page section to answer them all. In Surfer's 1,600 Gemini runs, only about 27% of fan-out keywords stayed consistent across searches, yet about 90% fell into four or fewer clusters. And 84% shared at least one URL with the original query's top 20 (Surfer, updated September 2026). You can't target wording that changes every run, but you can cover the clusters it falls into.
How do you prove the fix worked?
Re-crawl, compare the two audits, then re-run the queries you logged. Rubric's start_crawl and crawl_status run the new crawl, and compare_audits returns score_delta, fixed and regressed. A crawl can't tell you whether the engines changed their answers, so the re-run in ChatGPT and Perplexity is the real test.
The /mcp__citedscore__fix prompt runs Rubric's side of the loop inside Claude.
Answers churn between runs and after model updates, so date every result.
In Bing's sampled data, Copilot cited GoGoChimp 21,639 times in August 2026 and 8,678 times from 1 to 25 September. Without dates, a swing that size would make any fix I shipped look like a win or a failure.
Frequently asked questions
What is long-tail AEO?
Long-tail AEO is answer engine optimisation for the sub-questions AI engines generate from a prompt. Google's VP of Data Science and UXR, Shivani Mohan, says the average AI Mode search "is triple the length of a traditional Search query" (Google, 2026). The practical unit is the sub-question type, since exact wording changes between runs.
Why doesn't my keyword tool show these queries?
The AI writes sub-queries at answer time. Semrush found 65% to 85% of ChatGPT prompts matched no keyword in its 27-billion-keyword database (Semrush, 2026). Even classic search sees new queries daily: Google said in 2019 that "15 percent" of its daily queries were ones it hadn't seen before (Google, 2019).
How many sub-queries does Google AI Mode run?
Google hasn't published a number. It says AI Mode works by "issuing a multitude of queries simultaneously on your behalf", and that Deep Search "can issue hundreds of searches" (Google, 2025). Some SEO blogs credit an exact count to Google's May 2025 announcement, which doesn't contain one.
Why do AI answers cite different sources each time?
Each run can generate different sub-queries and pull different sources. AirOps tracked 800 queries and found only 30% of brands stayed visible in back-to-back responses. Only 1 in 5 held on from the first run to the fifth, and about 57% of brands that disappeared later came back (AirOps, 2025).
Can you get cited for a sub-question you don't rank for?
Yes. Floyi's study of 42 topical maps found 26.8% to 43.7% of AI citations went to sites that didn't rank for that query but ranked elsewhere in the same map (Floyi, 2026). Floyi sells topical-map software, and the data is correlational.
Is AEO different from SEO?
Google says it isn't. Its guide says "optimizing for generative AI search is optimizing for the search experience, and thus still SEO" (Google Search Central, 2026). What changes is that you're also answering the sub-questions an engine writes. More in our guide to optimising for AI search engines.
Start with the sub-question type you never appear for
Pick the type where your domain never showed up in the log, and give it one section on a page that already covers the topic. Ours was query clusters, at 1.11% in Bing's sample, and the definition above is our fix. If you'd rather start from the map than the log, run a Rubric audit.
References
- AirOps (Davidson, O.). (2025, 23 September). AirOps report on how citations and mentions affect visibility in AI search (800 queries, 45,000+ citations). https://www.airops.com/report/how-citations-mentions-impact-visibility-in-ai-search
- Brassell, N. (2026, 3 September). Ten Speed study of what AI cites at the B2B evaluation stage (170 prompts, 7,387 citations, via Peec AI). https://www.tenspeed.io/blog/what-ai-cites-b2b-evaluation-stage
- Capper, T. (2026, 21 August). Moz Whiteboard Friday on 10 fan-out types for prompt research. https://moz.com/blog/10-fan-outs-for-prompt-research-whiteboard-friday
- Ehrlinspiel, J. (2026, 29 September). Peec AI analysis of prompt-tracking accuracy (about 120 million chats, 8 assistants). https://peec.ai/blog/the-key-to-prompt-tracking
- Fishkin, R., with O'Donnell, P. (2026, 28 January). SparkToro research on AI inconsistency when recommending brands and products (600 volunteers, 2,961 runs). https://sparktoro.com/blog/new-research-ais-are-highly-inconsistent-when-recommending-brands-or-products-marketers-should-take-care-when-tracking-ai-visibility/
- GoGoChimp. (2026, 28 September). Bing Webmaster Tools AI Performance overview and AI search queries exports for gogochimp.com, data through 25 September 2026. First-party, unpublished.
- GoGoChimp. (2026, 12 May and 1 July). AI search citation tracker runs, BeeFriendly query on Perplexity and Google AI Mode. First-party, unpublished.
- GoGoChimp. (2026, 26 September). Rubric report for gogochimp.com (298 pages): Conversation coverage, Fan-out readiness and Queries to check. First-party.
- Google. (2025, updated 10 December). AI features and your website (Google Search Central). https://developers.google.com/search/docs/appearance/ai-features
- Google. (2026, updated 10 July). Optimizing your website for generative AI features on Google Search (Google Search Central). https://developers.google.com/search/docs/fundamentals/ai-optimization-guide
- Hardwick, J. (2026, updated 17 September). Surfer study of query fan-out rankings and AI Overview citations (10,000 keywords, Gemini-simulated fan-outs). https://surferseo.com/blog/query-fan-out-impact
- Harsel, L., et al. (2026, updated 7 April). Semrush analysis of ChatGPT search behaviour (US clickstream panel). https://www.semrush.com/blog/chatgpt-search-insights/
- Hsueh, Y. (2026, 2 September). Floyi topical authority report (42 topical maps, 29,319 topics, 354,955 citations). https://floyi.com/research/topical-authority-report/
- Linehan, L. (2025, 12 December). Ahrefs study of AI brand visibility correlations (75,000 brands). https://ahrefs.com/blog/ai-brand-visibility-correlations/
- Linehan, L. (2026, 2 March). Ahrefs study of AI Overview citations and the top 10 (863,000 keyword SERPs, 4 million AI Overview URLs). https://ahrefs.com/blog/ai-overview-citations-top-10/
- Long, C. (2026, 13 August). Nectiv data study of ChatGPT fan-out queries after the GPT 5.6 change. https://nectivdigital.com/blog/chatgpt-tripled-fan-out-queries-data-study
- Madhavan, K., Merchant, M., Canel, F., & Nigam, S. (2026, 10 February). Introducing AI Performance in Bing Webmaster Tools Public Preview. Bing Webmaster Blog. https://blogs.bing.com/webmaster/February-2026/Introducing-AI-Performance-in-Bing-Webmaster-Tools-Public-Preview
- Madhavan, K., Merchant, M., Nigam, S., & Shah, T. (2026, 16 June). New AI Visibility Insights in Bing Webmaster Tools: Intents, Topics, Citation Share, Compare. Bing Search Blog. https://blogs.bing.com/search/2026/6/New-AI-Visibility-Insights-in-Bing-Webmaster-Tools-Intents-Topics-Citation-Share-Compare/
- Mohan, S. (2026, 19 May). Google blog post on AI Mode usage in the US. https://blog.google/products-and-platforms/products/search/ai-mode-us-insights/
- Nayak, P. (2019, 25 October). Google blog post on BERT and search language understanding. https://blog.google/products/search/search-language-understanding-bert/
- Ong, S. Q. (2025, 20 August). Is ChatGPT Really Powered by Google? 118,931 Fan-Out Queries Analyzed. Ahrefs. https://ahrefs.com/blog/is-chatgpt-really-powered-by-google/
- OpenAI. (n.d.). ChatGPT search (Help Center). https://help.openai.com/en/articles/9237897-chatgpt-search
- Reid, E. (2025, 20 May). AI in Search: Going beyond information to intelligence. Google. https://blog.google/products/search/google-search-ai-mode-update/
- Rudzki, T. (2026, 5 May). Peec AI analysis of patterns in ChatGPT query fan-outs (5 million fan-outs, 1 to 21 April 2026). https://peec.ai/blog/patterns-we-see-in-chatgpt-query-fanouts
- Sadowski, J. (2026, updated 17 September). Surfer research on keyword query fan-out (1,600 Gemini runs). https://surferseo.com/blog/keyword-query-fan-out-research
- Sitter, N. (2026, 24 August). GPT-5.6 hotel search changes (616 destination-hotel prompts). https://www.nicolassitter.com/research/gpt-5-6-hotel-search-changes-2026
Free chapter
Read Chapter 1 of CITED, free.
The playbook for getting your business recommended by ChatGPT and AI search. Read the first chapter, on me.
Read Chapter 1 freeWant us to do this for your site?
Book a free AI audit. 15 minutes. We’ll show you three things your site is missing and what we’d test first.
Book my free AI audit →